An AI content factory is a structured software pipeline that ingests verified source material, applies controlled AI generation across discrete steps, runs deterministic quality checks, and presents drafted outputs to human editors for review. Rather than relying on single open-ended prompts, it treats content creation as an end-to-end engineering workflow designed for high editorial consistency and operational transparency.
Deconstructing the prompt box illusion
In many organizations, initial generative AI experiments begin and end inside a browser-based chat interface. An operator types a loose prompt, receives a block of draft text, and manually edits the result before copying it into a publishing system. While this approach can assist individual writers with ad hoc tasks, it fails to function as an institutional production system because it lacks standardized schema enforcement, reproducibility, and verifiable source controls.
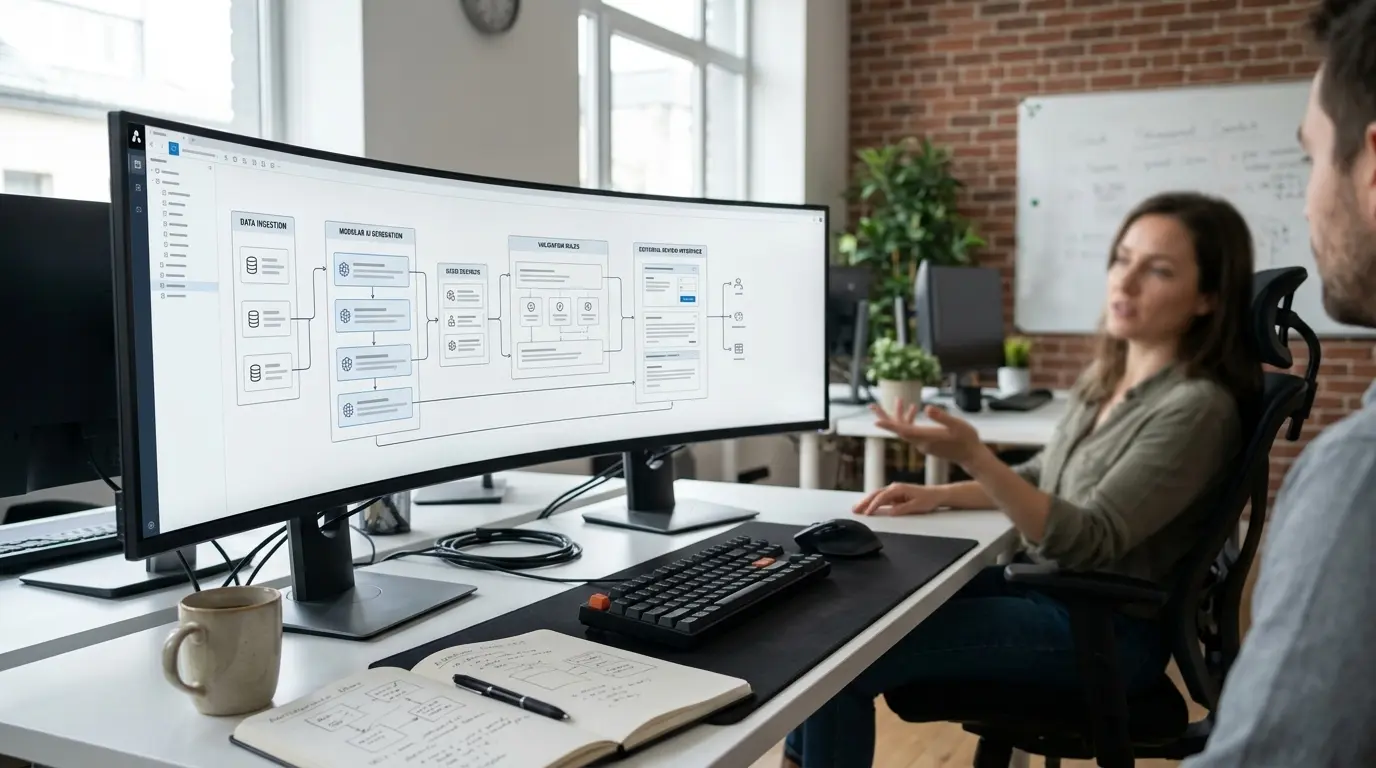
A practical production pipeline replaces unconstrained text prompts with structured inputs and programmatic orchestration. In a bespoke pipeline, content production is broken into sequential stages: data extraction, contextual grounding, modular generation, deterministic schema validation, and structured editorial review. Each stage has strict interfaces, logging, and failure recovery protocols.
If your organization requires custom pipeline engineering and end-to-end workflow software, explore our bespoke AI automation services. bespoke AI automation services.
Stage one: source ingestion and data structuring
Every reliable generation pipeline starts with controlled source data. Generating enterprise-grade documentation, catalog updates, or operational summaries requires verified source inputs rather than relying on an AI model's training memory. Raw information must be extracted from structured databases, product sheets, customer ticket transcripts, or approved knowledge bases.
Once ingested, the system parses, normalizes, and validates the raw text. Missing metadata fields, unverified factual claims, or incomplete references are flagged before any text generation occurs. The outcome is a structured payload containing only ledger-verified attributes, constraints, and contextual anchors ready for downstream tasks.
For teams seeking to feed engineering documentation into automated drafting systems, review our guide on capturing dispersed technical knowledge. capturing dispersed technical knowledge.
Stage two: decomposed modular generation
Attempting to generate an entire 2,000-word technical document, product catalog entry, or knowledge article in a single prompt causes hallucination, repetitive phrasing, and structural drift. Controlled pipelines solve this through modular task decomposition.
Instead of requesting a complete article at once, specialized agents handle narrow jobs in sequence. One agent generates the outline based strictly on verified inputs. A second component creates evidence-bounded section drafts. A third formats structured tables or validation schemas. By isolating each task, the system can apply task-specific prompt constraints and deterministic output validation.
Stage three: deterministic validation and constraint checking
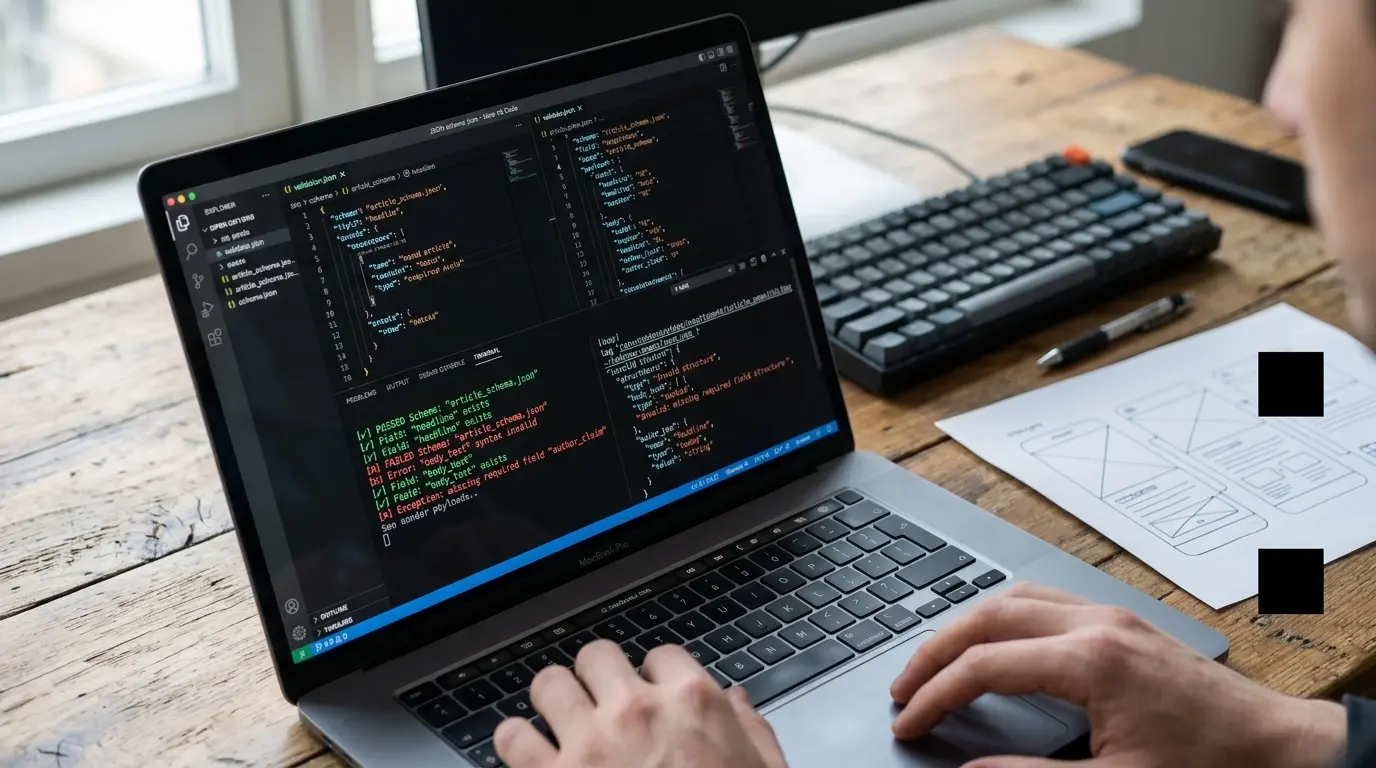
Before any generated draft reaches human eyes, it passes through automated validation layers. Unlike AI evaluation, deterministic checks execute strict code-based rules to verify JSON schema adherence, banned term exclusion, word count targets, and required data structures.
If a generation step produces invalid syntax, missing fields, or unauthorized claims outside the source payload, the pipeline rejects the output automatically. The system can then either re-trigger the specific modular step with corrective instructions or route the raw data into an exception queue for manual inspection.
Stage four: human review and editorial routing
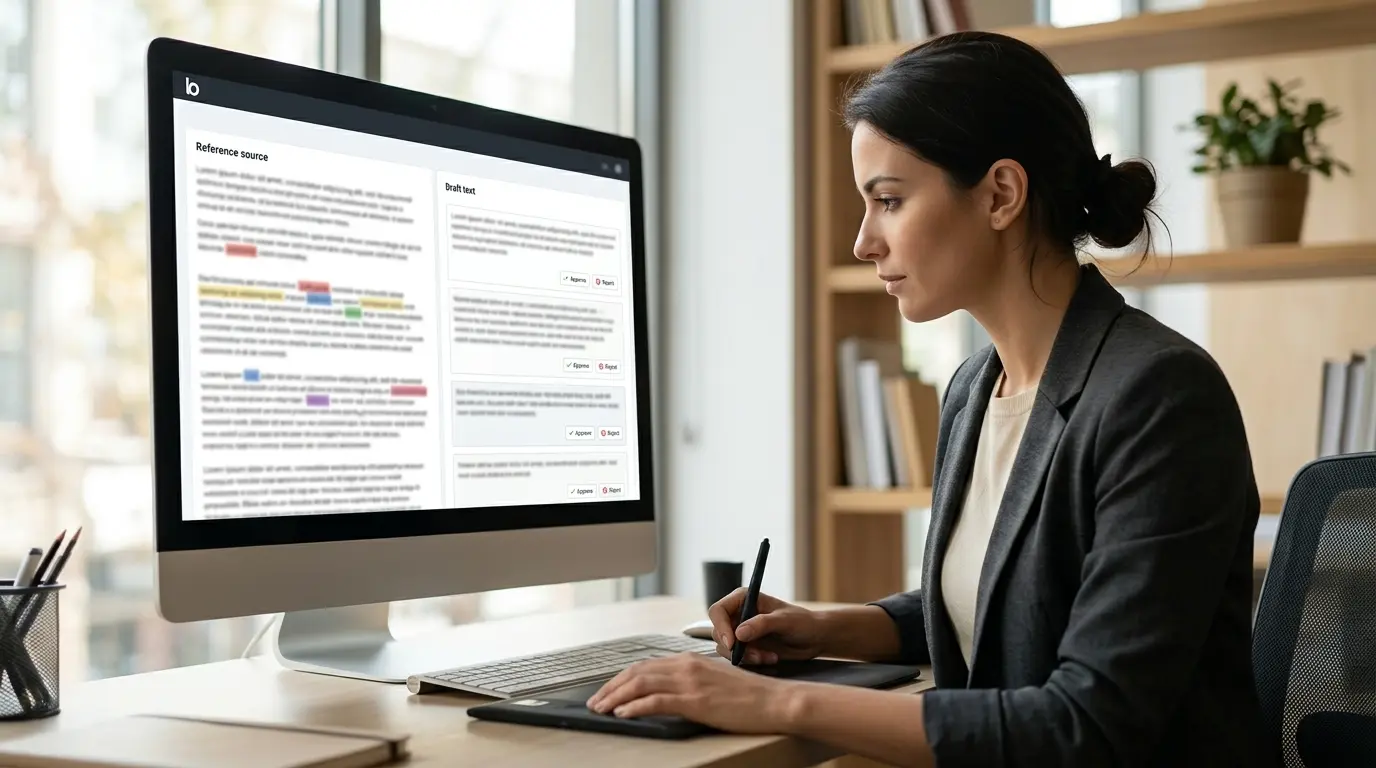
An AI content factory does not bypass human oversight; it structures and accelerates it. When a draft passes all automated validation gates, the pipeline loads it into a customized review workbench. Instead of reviewing a blank document, editors evaluate highlighted factual claims, inspect matched source documents, and approve or refine specific blocks.
Review interfaces allow subject matter experts to accept, modify, or reject modular sections individually. Approved records trigger automated serialization into target content management systems, while rejected sections provide structured feedback data to inform pipeline adjustments.
How custom automation studios build these pipelines
Engineering an end-to-end generation pipeline requires deep integration across internal systems, data repositories, and publishing destinations. Off-the-shelf wrappers often lack the granular error-handling, bespoke schema validation, and custom database connections needed for unique operational requirements.
Custom automation studios like YAS design and build bespoke pipelines from scratch. By mapping existing editorial and technical workflows, engineering custom orchestration software, and embedding human-in-the-loop validation tools, custom engineering ensures the resulting pipeline integrates directly with your enterprise infrastructure.
To understand how autonomous agent steps interact with rigid workflow code in content pipelines, explore our analysis contrasting agentic approaches with workflow automation. contrasting agentic approaches with workflow automation.
Limitations and suitability
An automated content factory is not suitable for every business scenario. It is ineffective for speculative creative writing, ungrounded opinion pieces, or operations lacking structured, verified reference data. If your core inputs are ambiguous or frequently contradicted across systems, automated generation will simply amplify those data inconsistencies.
Organizations must verify their underlying source quality, API stability, and editorial governance before deploying an automated generation pipeline. Furthermore, automated pipelines do not eliminate the necessity of subject matter expert review, nor do they guarantee absolute factual accuracy without continuous monitoring and maintenance of verification checks.
- Audit source data quality and accessibility before designing generation workflows.
- Define explicit validation schemas for every content type to prevent structural drift.
- Establish human review protocols to verify tone, context, and domain-specific nuances.
When determining which operational workflows to automate first across your organization, see our framework on identifying initial processes for automation. identifying initial processes for automation.
Maintaining pipeline performance over time
Operating a content factory requires ongoing maintenance. As underlying models evolve, prompt templates may exhibit subtle behavioral shifts, requiring version tracking and regression testing across standard test suites.
Teams must monitor execution latencies, token consumption, automated validation failure rates, and editor rejection patterns. Regularly reviewing these operational metrics allows engineers to refine prompt constraints, expand automated checks, and maintain consistent output quality.
| Pipeline Component | Primary Function | Execution Mechanism | Failure Handling |
|---|---|---|---|
| Data Ingestion | Extracts and normalizes approved reference data | Deterministic API and database connectors | Payload rejected if required fields are missing |
| Modular Generation | Drafts discrete content sections against strict bounds | Controlled AI agent execution per schema | Automated retry with tightened constraint prompts |
| Deterministic Validator | Verifies schema, banned terms, and structural integrity | Code-based validation rules (e.g., JSON schema) | Routes malformed drafts to an exception queue |
| Editorial Workbench | Enables human verification and modular sign-off | Custom human-in-the-loop review interface | Manual rejection sends feedback to pipeline logs |
| Publishing Dispatcher | Formats and syncs approved drafts to CMS endpoints | Bespoke webhook and API integrations | Execution logs alert engineering to connection drops |
Steps to implement an end-to-end AI content pipeline
- Map the end-to-end content production process and identify verifiable data sources.
- Define strict JSON schemas and validation criteria for each target content format.
- Build automated ingestion connectors to extract and normalize reference documentation.
- Decompose generation tasks into discrete modular steps with specific prompt boundaries.
- Implement programmatic validation checks to enforce formatting and banned-phrase rules.
- Develop a specialized human review workbench with source-comparison capabilities.
- Deploy bespoke publishing integrations to sync approved outputs directly into target systems.
A practical content factory is an engineering pipeline: it couples verified source data with modular generation and deterministic code checks to make output reliable.
FAQ
How does an AI content factory differ from using conversational AI tools?
Conversational tools rely on open-ended chat prompts in a browser, producing variable results without schema constraints. An AI content factory is a structured software pipeline that decomposes creation into automated data ingestion, modular task generation, deterministic validation checks, and systematic human review.
Why is task decomposition necessary in content generation pipelines?
Generating an entire long-form asset in a single prompt often introduces hallucinations, structural drift, and formatting inconsistencies. Decomposing the process into discrete steps, such as separate tasks for structuring, drafting, and validating, allows strict boundary controls and automated error handling at each stage.
What role does deterministic validation play in the pipeline?
Deterministic validation uses programmatic code checks to ensure outputs strictly adhere to required JSON schemas, word limits, and formatting rules. It rejects malformed or unverified drafts automatically before they ever reach human editors.
Does an automated content pipeline eliminate the need for human editors?
No. An automated pipeline handles data extraction, structuring, initial drafting, and formatting, but human subject matter experts are essential for verifying domain accuracy, reviewing nuanced context, and approving final publication.
What types of content are best suited for an automated factory?
Content types with structured source data and clear repeatability are best suited. These include technical documentation, catalog descriptions, knowledge base guides, and standard operational reports where factual consistency is critical.
How can teams get started with custom content automation?
Begin by documenting existing content workflows, verifying source data completeness, and defining explicit validation rules. From there, engineering teams can build modular ingestion, generation, and review systems tailored to specific operational requirements.